Advanced workshop mechanics
Measured alignment

Seemingly clear workshop results can conceal consequential differences in judgment. If those differences go unseen, priorities, decisions, and next steps may rest on the false assumption that the group agrees. You also miss the opportunity to ask what lies behind those differences. Are participants drawing on different information or assumptions? Is the group about to overlook something consequential?

The problem: legacy workshop mechanics cannot reveal such misalignment reliably. In a group conversation, only one person speaks at a time. Much of what the group thinks about the point at hand remains unspoken. Reading the room is the best those mechanics allow. But even with keen observation, those inferences remain guesswork.

With XLeap, you replace guesswork with measurement. XLeap shows precisely where judgments align, where significant differences exist, and what may need closer examination.

See where judgments align · Pinpoint significant differences · Know what needs attention
Request a demo

Undiagnosed misalignment invites failure

Hidden misalignment can undermine a workshop long before anyone makes a decision based on its results. This isn't a theoretical point: While strong opposition usually becomes visible, especially when emotions run high, consequential differences in judgment routinely remain hidden.

For example, participants may agree that Measure X would be highly effective yet disagree sharply on whether it is feasible. Such differences may point to real obstacles, conflicting assumptions, or missing information. Unless those differences become visible, the person running the workshop has no reliable basis for investigating their causes. With many topics to cover and limited time, investigating possible disagreements on a hunch is not a practical option.

Decision-makers may then receive an apparently clear recommendation without knowing that a significant part of the group considered the measure infeasible, let alone why.

To ask the right questions, you need to know exactly where and how participants' judgments diverge.

Reading the room cannot solve it

Imagine 15 participants assessing 50 ideas against three relevant criteria. That produces 2,250 individual assessments across 150 item-and-criterion combinations.

Inferring how closely those judgments align from verbal and nonverbal signals in real time is impossible. But computational ability is not the real constraint. With legacy workshop mechanics, only a fraction of the required information is observable.

Group of smiley emoticons with clearly different facial expressions.

Is this group aligned on the feasibility of
proposed solution 17?

Even that fraction is difficult to interpret. Most workshops bring together people with different expertise and perspectives because the task requires it. There is no reason to expect the person running the workshop to know all participants well. They may differ considerably in temperament, cultural background, and how they express themselves. Without a personal baseline, how can the person running the workshop be expected to tell whether someone is unusually agitated, dismissive, or enthusiastic—or simply behaving as they normally do? Knowing some participants better than others introduces a further distortion: their reactions may receive disproportionate weight because they seem easier to interpret.

And even an accurately interpreted expression does not identify its cause. A reaction may concern the substance of an issue—or personal relationships, hierarchy, prior positions, or something else entirely. Silence may mean agreement, reluctance to challenge, deference, or simply a preference not to speak.

Conferencing compounds these difficulties. Nonverbal cues are reduced, fragmented across small video windows, or absent altogether. But the fundamental limitation exists in-room too.

Suppose every expression in a room were as easy to interpret as the smiley emoticons in our illustration. They are, after all, designed to convey an emotion. Even perfect interpretation would tell the person running the workshop something about participants' moods, not how each judges, for example, the feasibility of a particular measure.

This is not a failure of facilitation. It is a structural information gap no degree of experience or sensitivity can close. Expecting anyone to determine alignment by reading the room is asking the impossible.


Selection counts do not show where judgments align

Assessment and prioritization are the obvious occasions to collect data on how closely judgments align. All the more striking, then, how thoroughly legacy rating methods fail at that task.

Sticky-dot voting, likes, and similar methods reduce judgment to selections. A dot tells us that someone selected an item. The absence of a dot does not tell us whether the item narrowly missed the cut, seemed irrelevant, or was judged actively harmful. Selection counts cannot show how judgments differ—whether participants are closely aligned or sharply divided, or agree on one criterion and disagree on another.

Moreover, these selections are often not made independently. In sticky-dot voting, participants place their dots in full view of the group. What appears to be agreement may just reflect perceived expectations.

The commonly used alternative is to let participants place their dots unobserved. But that creates another problem: Everyone waits. First for their own turn. Then for the others to finish. Whoever is up feels pressure to get their dots down and move on. Each participant's reflection time shrinks to a fraction of the total voting time. And somehow, new dots gravitate toward those already there.

Sticky-dot voting only records selections. It does not provide the data needed to measure alignment.
Sticky dots are distributed across several abstract options.

Sticky dots: no alignment data.

XLeap Rating produces the data

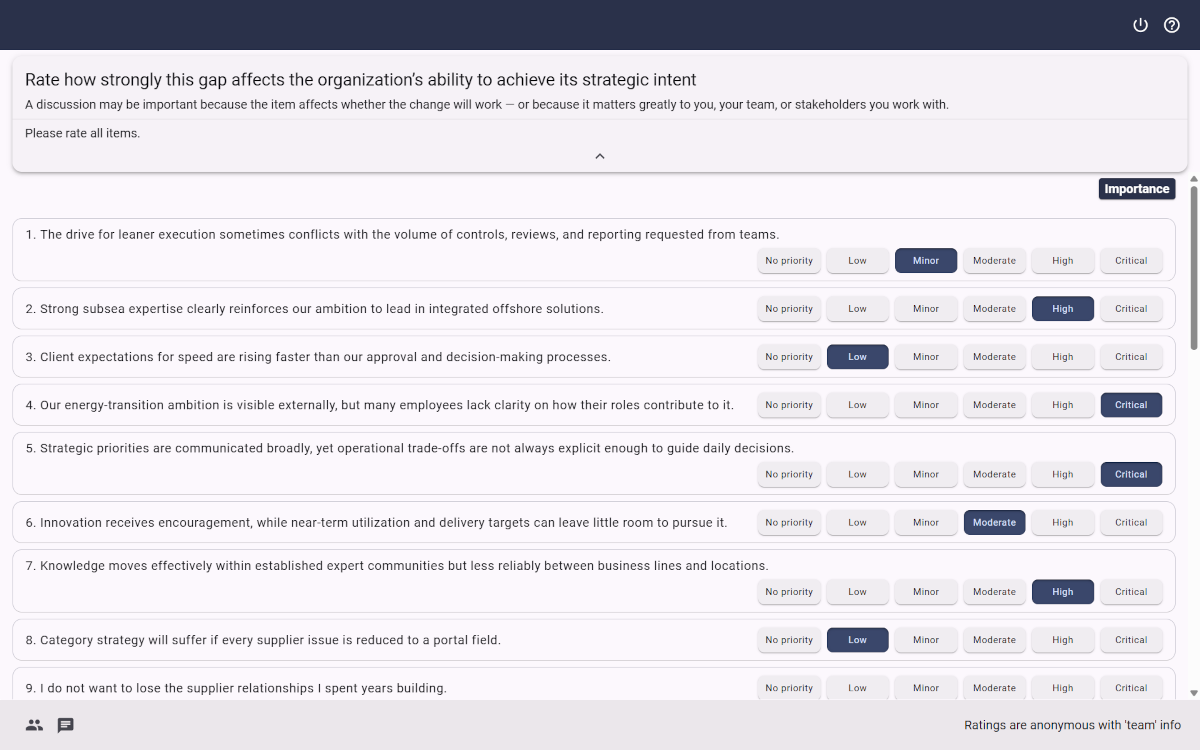
Rigorous prioritization is one of XLeap’s six workshop mechanisms. With XLeap's differentiated rating methods, each participant assesses every item rather than merely selecting some of them. These individual judgments can be compared.

Items can be assessed against multiple criteria—for example, measures by their impact and feasibility. XLeap measures alignment for every item and criterion.

Participants complete electronic Rating sheets simultaneously. The group moves quickly while each participant has enough time to consider their ratings carefully.

Because XLeap Rating is fast and precise, you can use it whenever you need a dependable assessment by the group: Which topics matter most? Which ideas are strongest? Which measures should be pursued?

A participant rates each item's importance on a 0–5 scale.

You determine the relevant criteria and choose the rating method. XLeap offers a wide range of numerical scales, including bipolar scales with or without a neutral midpoint. Other methods include Rank order, Estimate, and Budget allocation. For specific use cases, XLeap also supports Multiple selection.
Only measure alignment when judgments are independent

Participants submit their assessments independently. They do not see how others are rating, which protects against social pressure to align their assessments with a perceived majority. Where simply following others would be easier than forming an independent judgment, XLeap removes that shortcut.

To support honest and candid judgment, most professionals run Rating anonymously. That matters for measuring alignment. Without anonymity, participants know that their ratings can come back on them. Fear of criticism or damaging relationships, deference to hierarchy, favors owed, or later repercussions can influence the judgment they are willing to put on the record. With anonymous Rating, that personal exposure is removed.

In short, XLeap keeps conformity pressure from masquerading as alignment.
An average can hide disagreement

Even the results of differentiated rating methods can be ambiguous. An average tells us where the group lands in its judgment—but only on average. It does not show whether the group is closely aligned or sharply divided.

Very high or very low averages on a rating scale are usually clear enough. On a scale from 0 to 10, a very high average means that most participants rated the item highly. A very low average means that most rated it low. One or two outlying judgments change little.

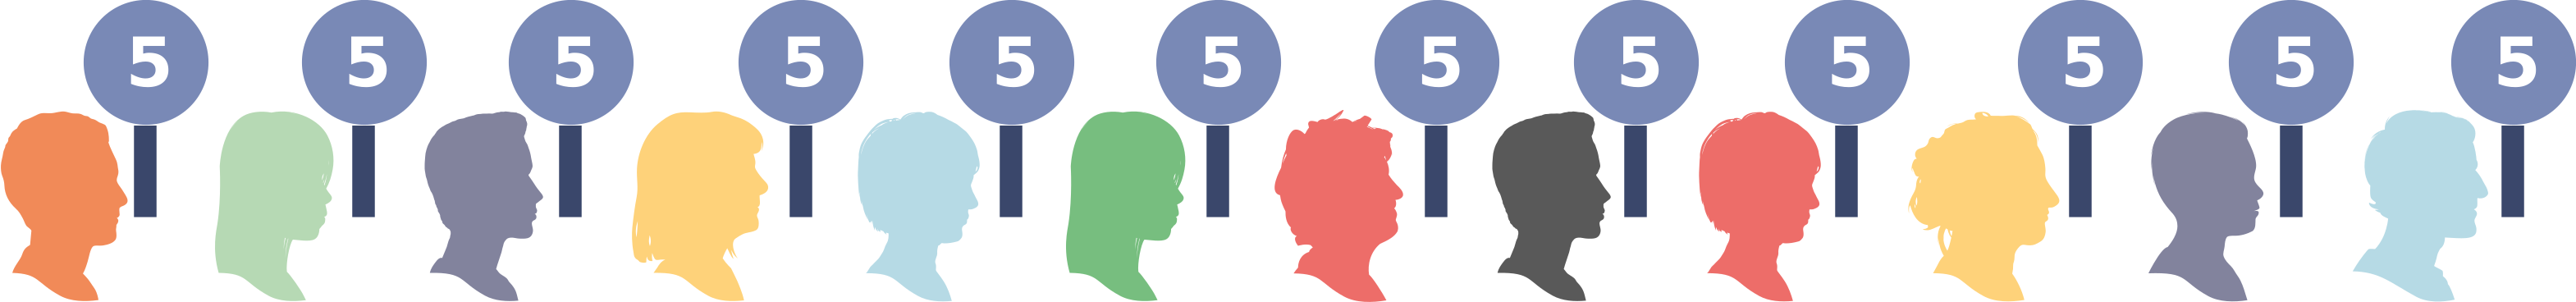
With middling values, it is different. Consider an average of 5 on a scale from 0 to 10.

Abstract graphic of a jury of 12 unanimously awarding 5 points.

We agree completely: it is mediocre.
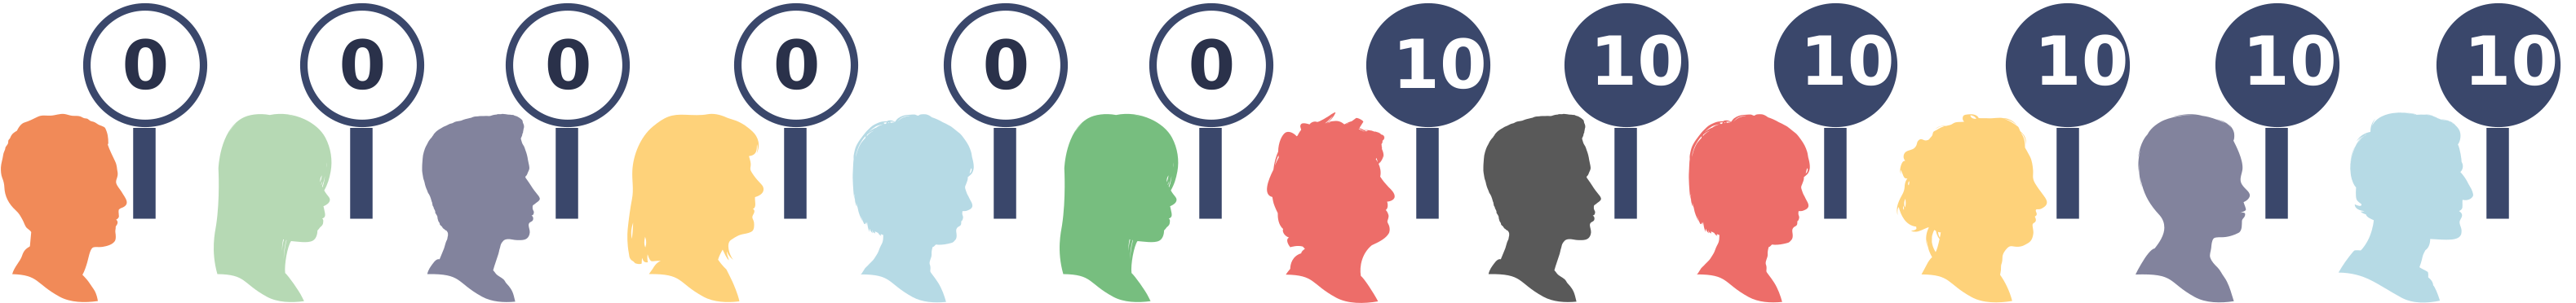
Abstract graphic of a jury of 12. Six jurors award 0 points while the other six award 10 points.

We could not disagree more.

The average is identical. What it means is not.

XLeap calculates standard deviation, a measure of how widely individual ratings are spread around the average. The closer the ratings are to one another, the lower the standard deviation. The further apart they are, the higher it is.

XLeap normalizes this value for the rating method used. The normalized standard deviation, or nSD, provides an easily understood and consistently interpretable indicator of alignment for every assessment.

A low nSD value is informative too. It shows when an average genuinely reflects a shared judgment.
Alignment data must be usable

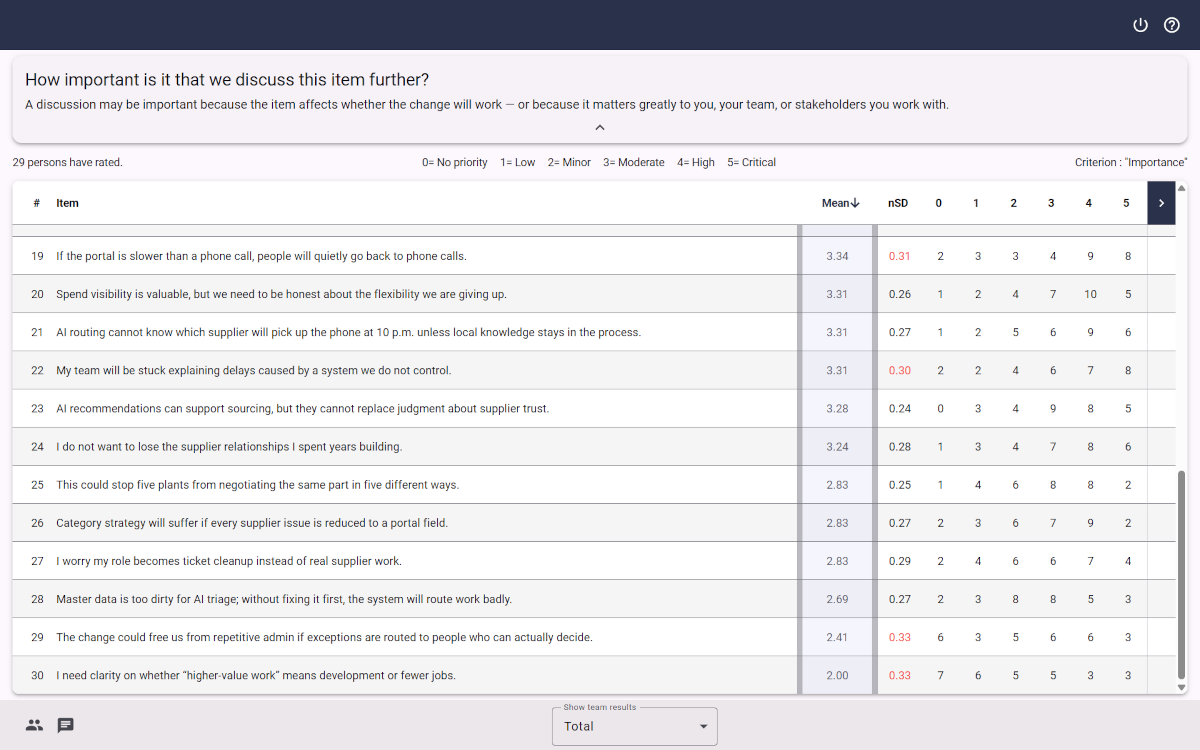
When XLeap measures alignment across many items and criteria, it generates a wealth of additional information. XLeap Results tables make that information usable for group work. They show nSD alongside the rating result and can be sorted by it. The Host sets a threshold above which high nSD values are highlighted. Strong differences stand out immediately. When the group wants to go into detail, the table shows the distribution of individual ratings behind the indicator.

In multi-criteria Results tables, color-coded threshold analysis makes patterns visible—for example, strong alignment in the assessment of effectiveness alongside strong differences in the assessment of feasibility. If a Results table is complex—for example, because it combines several metrics across multiple criteria—you can initially hide information. Complexity builds gradually, making the content easier to grasp. The design principle is depth on demand.

With alignment measured, participants can see that differences in judgment do not simply disappear into the overall result. They can also see when objections have little support. If the group then moves on, that does not mean objections were suppressed. It means too few participants shared them.

A minority judgment may still matter for substantive reasons. Whether it matters remains a matter of professional judgment. A controversial idea may deserve closer examination. Or it may not, because there may already be more strongly and broadly supported options than the group can pursue.

Single-criterion results table with high nSD values flagged in red.
Detail shows distribution of ratings.
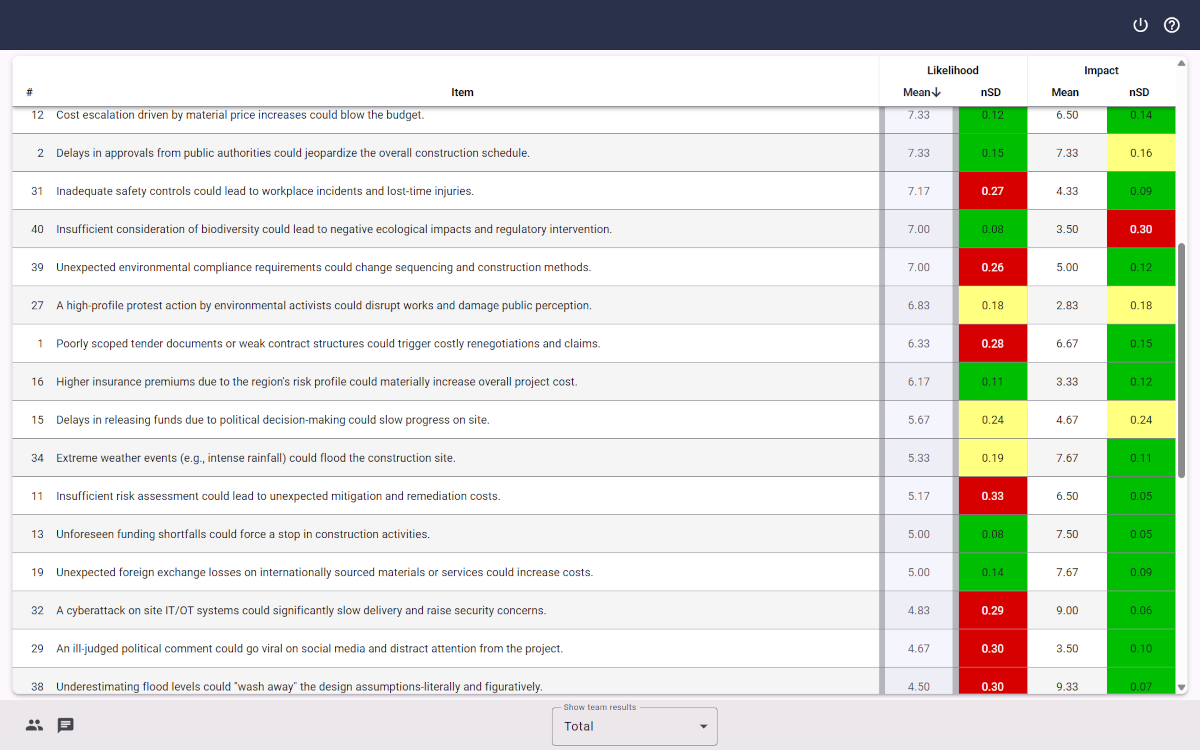
Multi-criteria results table with nSD values color-coded
in a traffic-light scheme with custom thresholds.

Tables and charts let you analyze priorities and alignment with the group, examine the differences that matter, and decide what the group should do next.
See how the divide runs

Depending on the question at hand, it can matter how judgments are distributed within and between particular participant groups. The Host can define relevant participant groups for that purpose. Ratings can be associated with those groups without identifying individual participants. Personal anonymity is preserved.

If feasibility is at issue, for example, distinguishing between participants close to implementation and those further removed from it can be revealing. The judgment of those close to implementation may warrant greater weight because of their proximity to the work. Strong alignment within that group additionally shows that the judgment is broadly shared.

When assessing a go-to-market strategy, it may matter whether differences cut across the group or run between Marketing and Sales. In product development, differing judgments from R&D, Marketing, and Operations may be relevant.

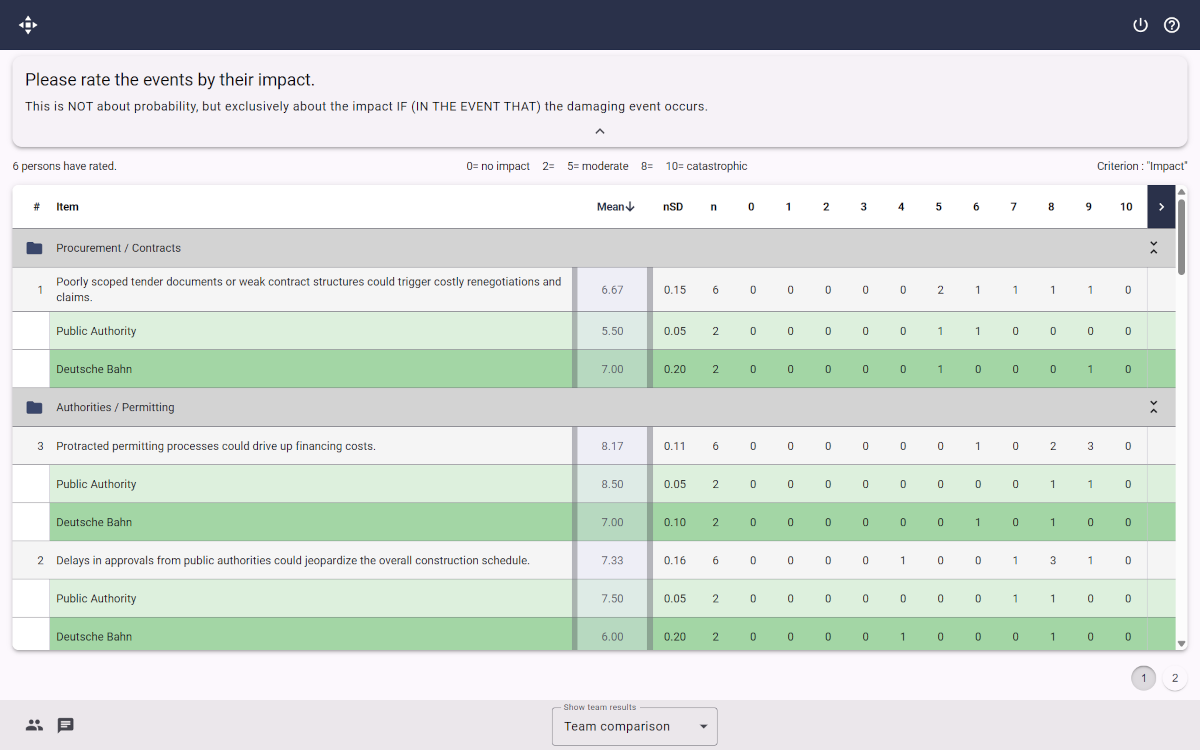
You decide whether participant-group analysis is useful and which groups matter to the question at hand. XLeap supports the analysis with Results tables and charts that show ratings and alignment for the defined participant groups and make differences between them visible.

Single-criterion results table structured by item category 
with detailed results for "Total" and two subgroups. 
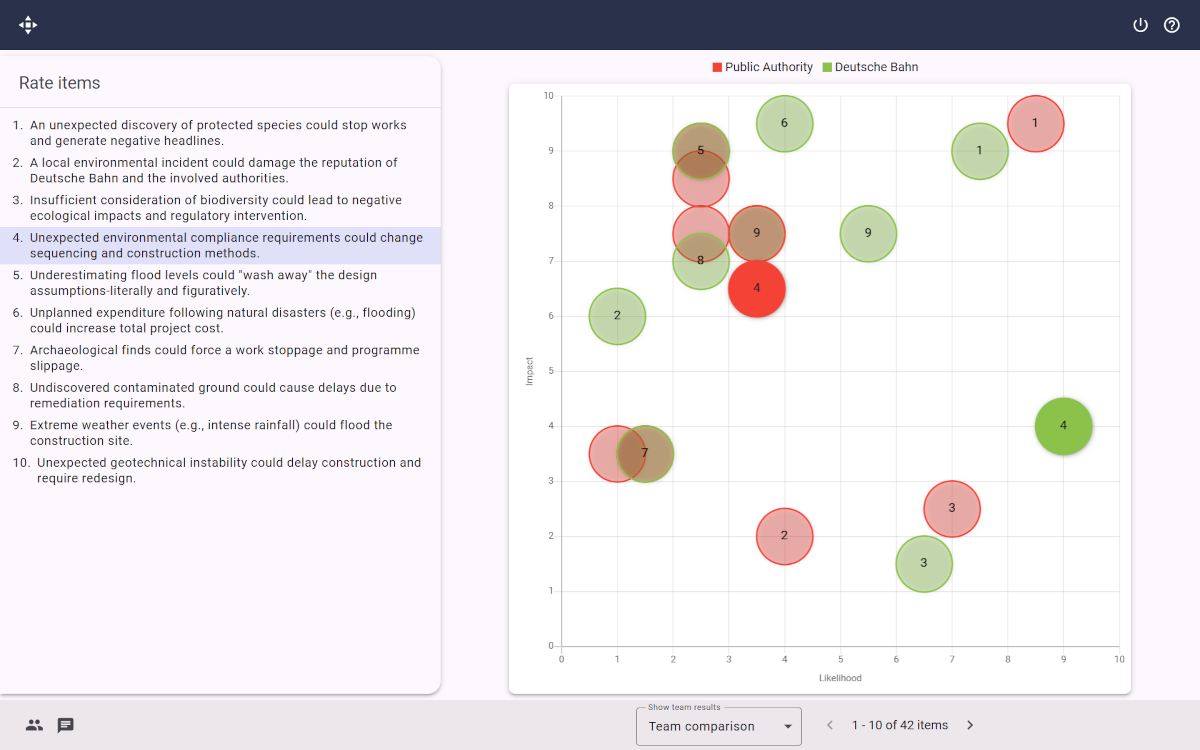
Multi-criteria results chart comparing results of two subgroups.
Focus is on item 4.
Interlocking mechanisms

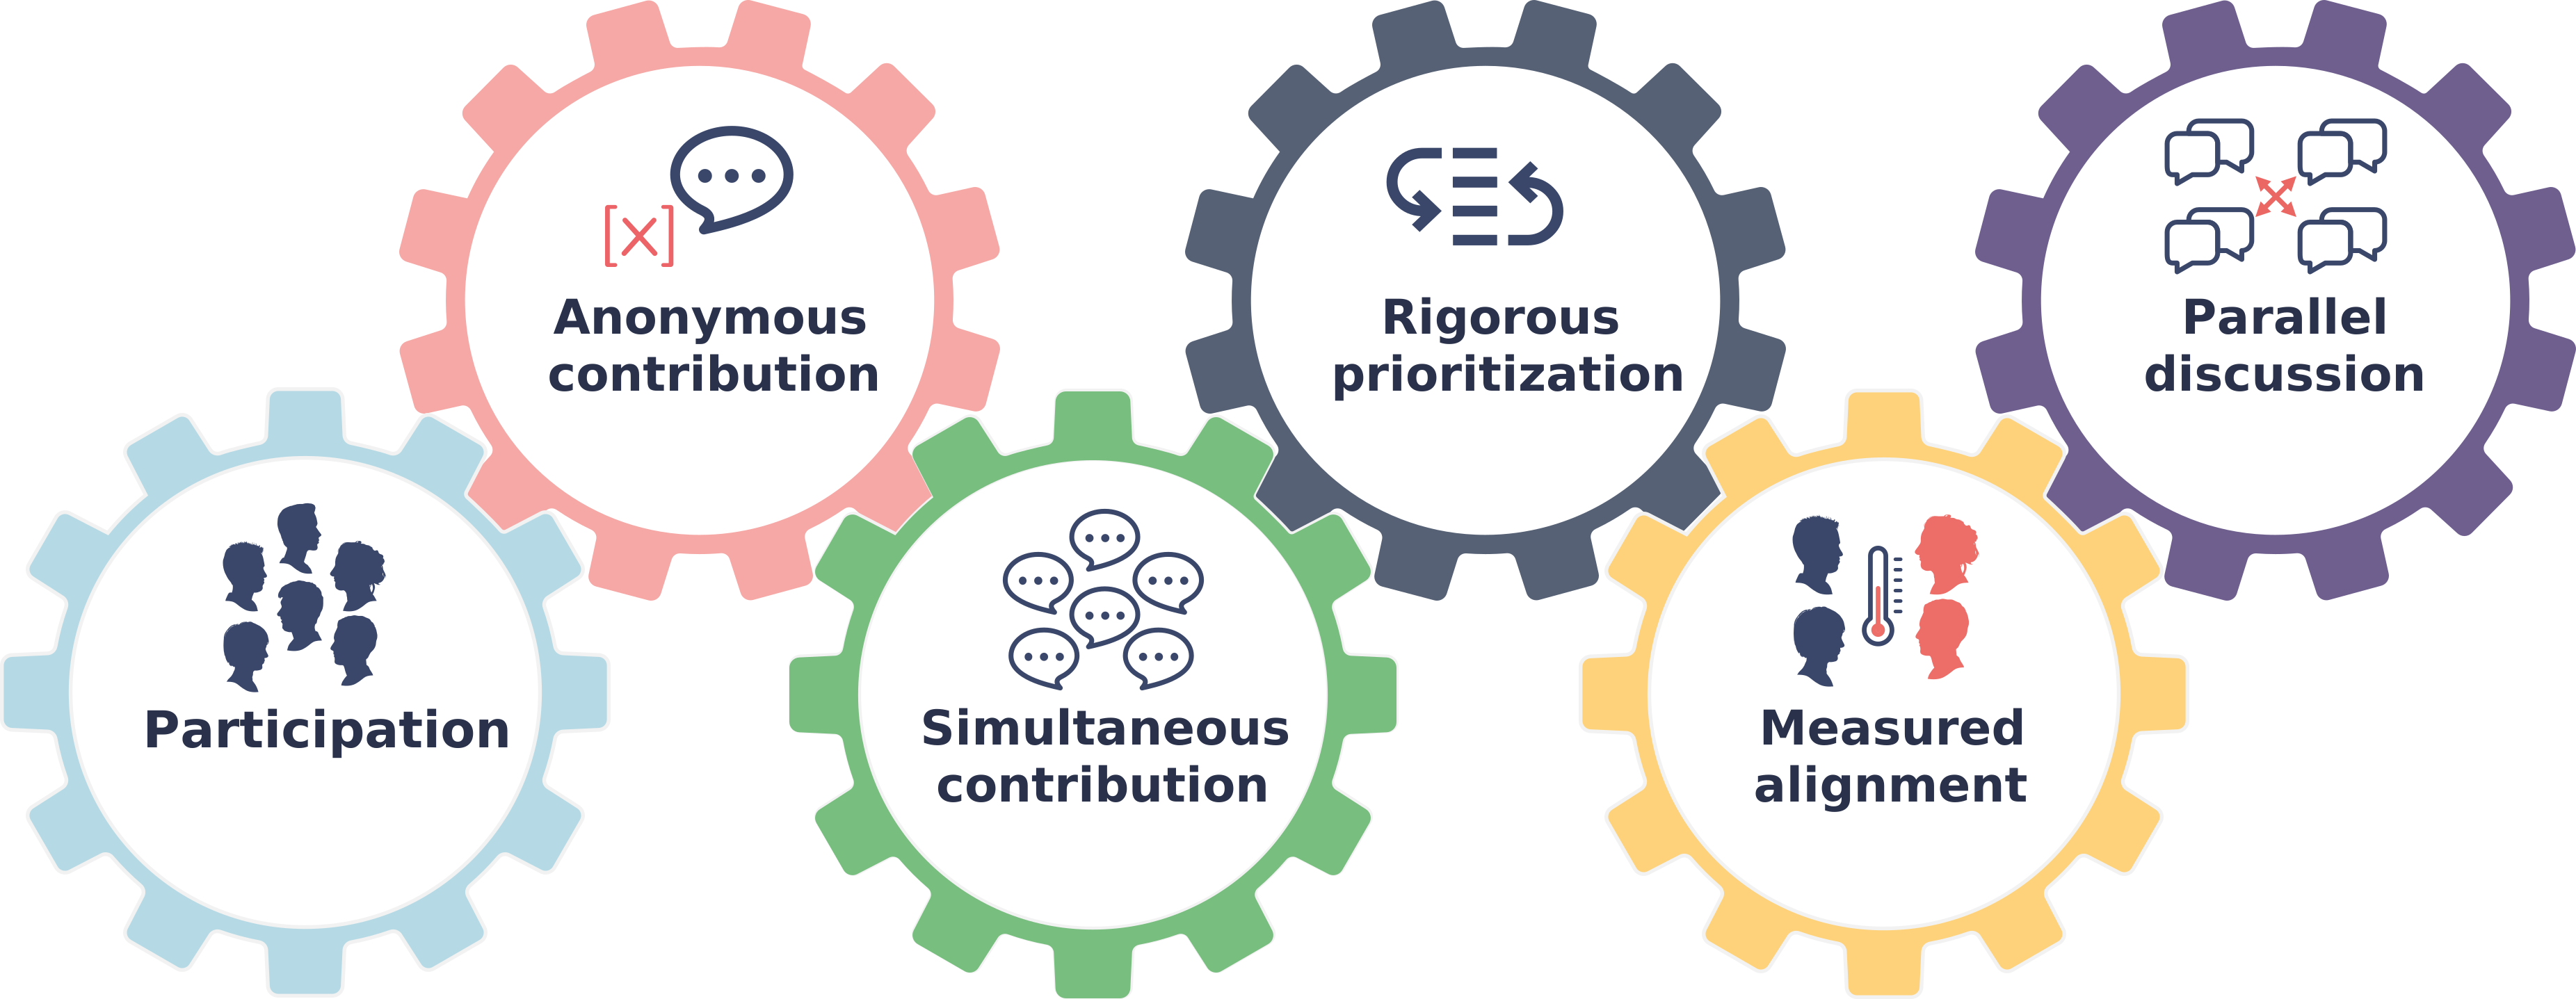
XLeap’s six workshop mechanisms reinforce one another.

When participants can contribute simultaneously, you can broaden participation to include everyone whose knowledge and judgment you need. Anonymity lets them say openly what they know and think without exposing themselves personally. Their contributions can be judged on substance rather than on who made them.

Six interlocking cogwheels representing XLeap’s workshop mechanisms.

Together, the mechanisms produce stronger solutions and more robust decisions.

With rating methods and criteria suited to the task, the group determines what matters most. XLeap automatically measures where judgments align and where significant differences exist.

The group can examine several important or contested topics in depth at the same time without splitting up. In these discussions, participants can contribute simultaneously and, when useful, anonymously.

Put alignment to work

Strong alignment among relevant experts and stakeholders gives recommendations and conclusions greater weight. Significant differences show where assumptions, evidence, feasibility, or support warrant closer examination.

Crucially, you can clarify conflicting assessments and contested assumptions directly with the group. Facts replace guesswork before conclusions are drawn.

See where judgments align · Pinpoint significant differences · Know what needs attention

Request a demo

EXPLORE FURTHER

Use cases · Rating workspace